PROJECT
ViT-Assembler
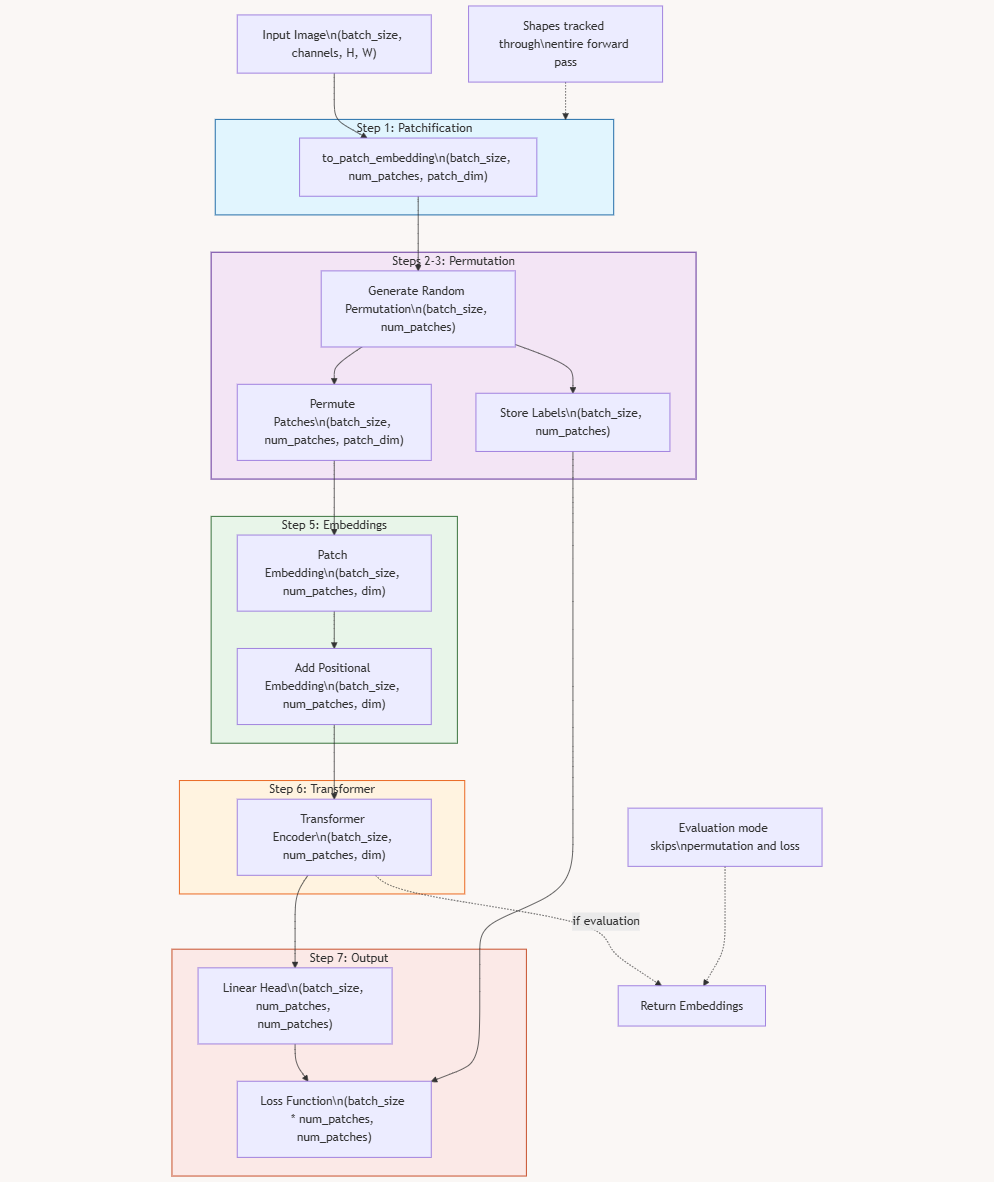
A self-supervised Vision Transformer learns image representations by solving a jigsaw-style pretext task: image patches are shuffled and the model predicts their original positions. The repository includes the model overview and training experiments.