PROJECT
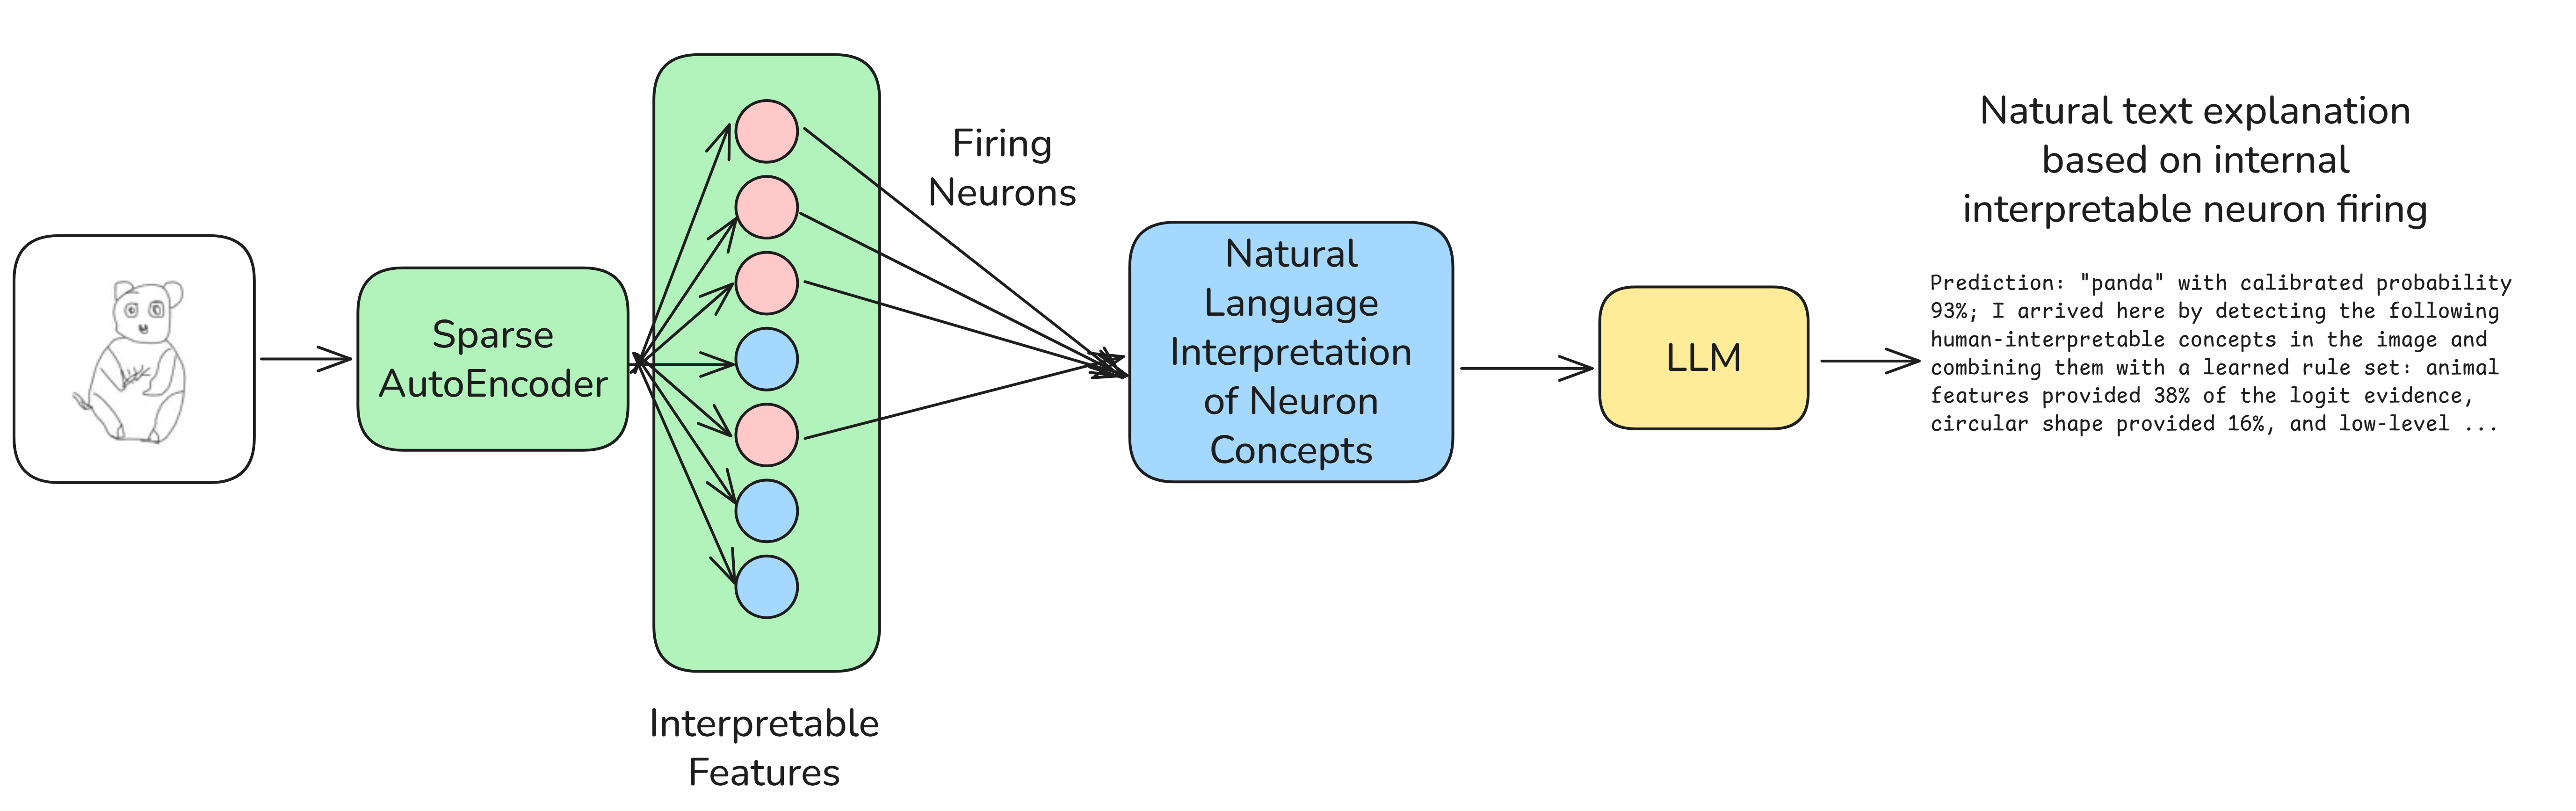
Self-Explaining Classifiers with Sparse Autoencoders and LLMs
A classifier explanation pipeline that fits a sparse autoencoder to an intermediate CNN feature map, turns learned activations into human-readable concepts, and uses those concepts to explain individual predictions.